NexGPU
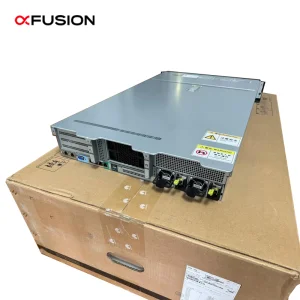
In the era of hyper-scale computing, the demand for density-optimized hardware has shifted. As a leading manufacturer, NexGPU identifies that global enterprise procurement is prioritizing energy efficiency and high-density computing clusters for AI inference. By leveraging semantic-optimized manufacturing, we ensure our server architectures align perfectly with evolving workload requirements, from edge data centers to cloud-native AI clusters.
NexGPU's 120-engineer R&D team is currently pioneering advancements in thermal management and liquid cooling for high-TDP processors. Our roadmap focuses on integrating modular NVMe architectures and AI-driven predictive maintenance to minimize downtime, ensuring that our partners remain ahead of the curve in machine learning and deep-learning operations.
We provide localized hardware configuration and full compliance with international standards (CE, FCC, RoHS, ISO). Our supply chain resilience, supported by over 1,200 strategic partners, allows us to mitigate lead-time risks even during periods of global component shortage.
Thanks to our robust supply chain in Shenzhen, we typically ship custom orders within 15-25 business days.
Yes, we provide end-to-end integration for AI inference, including GPU optimization and rack-level testing.
Every unit undergoes burn-in, compatibility validation, and reliability testing before global export.